No stable public corpus count or quality benchmark is published yet. The case study reports the architecture and its boundary without inventing a score.
Architecture and source evidence onlyReviewed 2026-08-31Case 03 / Public-interest information system
Tathya
Tathya preserves who said what, where it came from, and what remains unresolved without pretending that a language model can issue the final verdict.
- Role
- Product engineer
- Built at
- Personal project
- Contribution
- Product, ingestion, evidence model, and interface
- Status
- In progress
Measured, with the denominator attached
Proof before polish.What it is
01 / What it is
A case file that keeps the source trail attached.
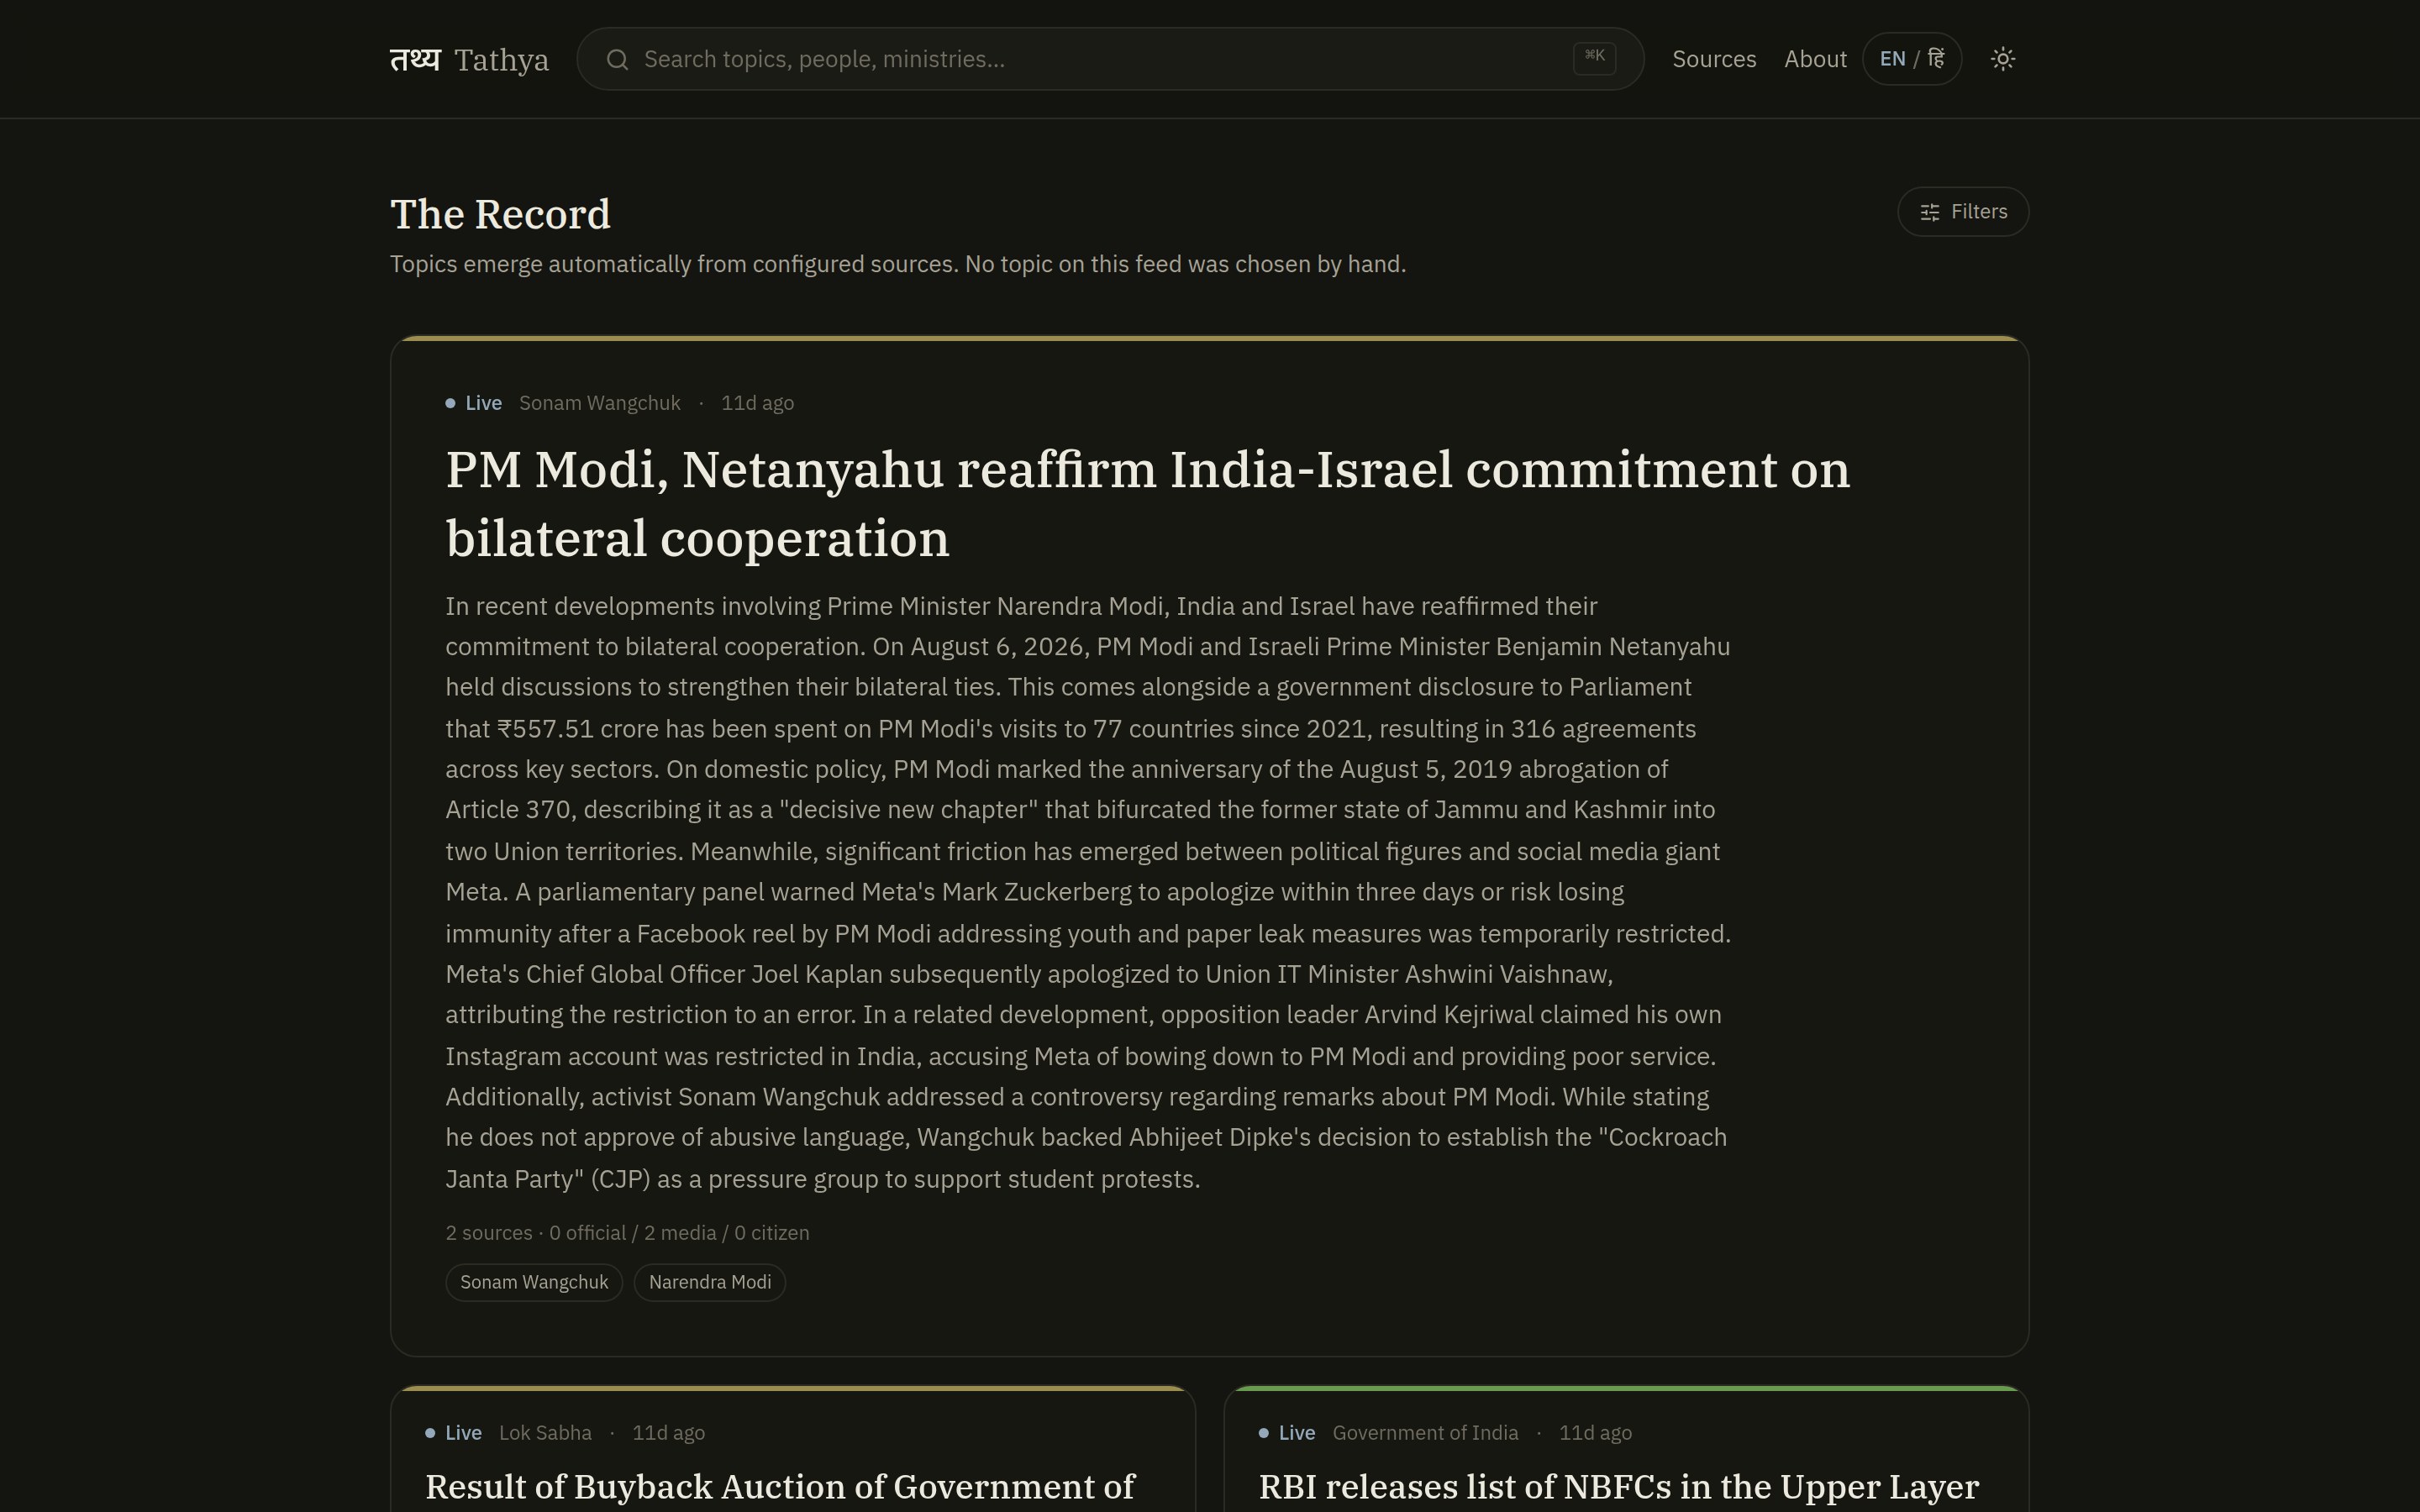
Tathya collects material from official and editorial sources and organises it into cited case files.
The reader can inspect the source trail instead of receiving a synthetic truth score.
Built for
Readers, researchers, journalists, and civic teams that need a sourced record of institutional and editorial claims without receiving an opaque truth score.
I designed and built the source ingestion, duplicate handling, topic identity, claim clustering, case-file workflow, product interface, and the boundary that removes verdicts and source ranking from the product contract.
Contribution record
02 / Product proof
See the actual product before reading the argument.
Real product recording
01
Official and editorial material enter as separate source records so provenance survives later grouping.
02
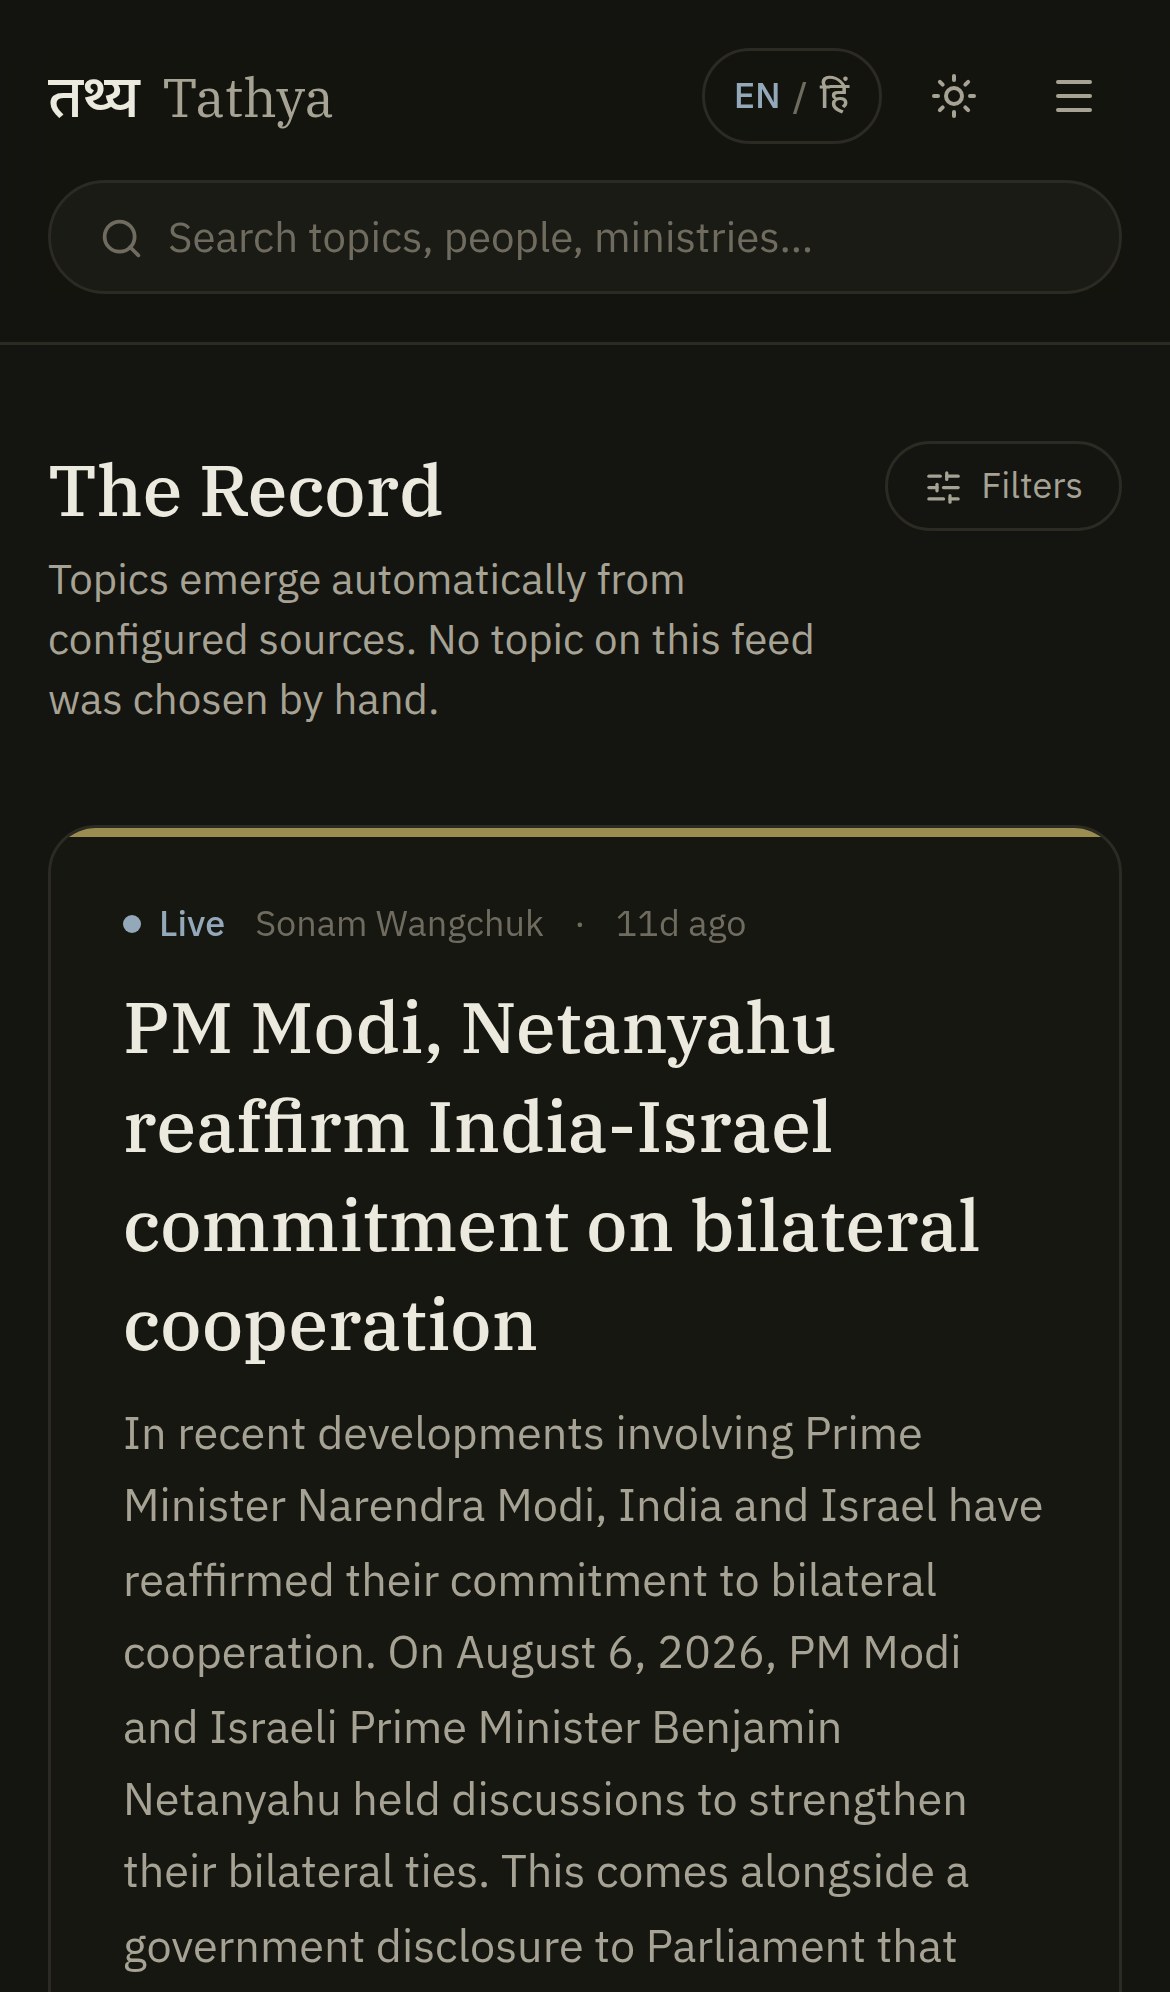
The mobile surface preserves the same source-first reading path without collapsing disagreement into a score.
03
- Input
- Official and editorial source records
- Grouping
- Duplicate handling, stable topic identity, and cited claims
- Output
- Sourced case file
- Not produced
- Verdict, ranking, or sentiment score
A case file may group related claims and citations, but the unresolved state stays visible when the evidence cannot support a conclusion.
03 / Problem and responsibility
Organising disagreement is useful. Pretending to settle it is not.
Summarisation systems are rewarded for collapsing disagreement into one answer. Political records often need the opposite: sources kept distinct, dates preserved, and uncertainty left visible.
The product has to remain useful without silently ranking publishers or manufacturing a verdict.
- Product
- Mission boundary, reader workflow, case-file structure, and the removal of verdict language.
- Data
- Source ingestion, normalisation, duplicate handling, stable topic identity, claims, citations, and database workflow.
- Interface
- Responsive public record, source visibility, unresolved states, and failure-facing copy.
04 / Research that changed the build
Research only matters here when it changed a decision.
- 01
Official and editorial source separation
Publisher role is part of the evidence context and should not disappear during normalisation.
The source model preserves provenance and source type instead of flattening every item into interchangeable text. - 02
Mission and ethics review
A truth score would transfer editorial authority to a system whose evidence can be partial, duplicated, or stale.
Verdicts, sentiment ranking, and publisher scoring were removed from the product contract. - 03
Stable topic identity and duplicate failure review
Repeated ingestion could create stale duplicate claims and split one continuing subject across several case files.
Duplicate handling and durable topic identity became upstream requirements rather than presentation cleanup. - 04
Generation error and promotable-gate audit
Silently swallowed generation failures and a suppressive promotable gate could hide records rather than explain why they were incomplete.
The gate was removed from the publishing contract and incomplete processing now belongs in visible workflow state.
05 / Architecture
Make the source and claim graph the product, and remove verdict generation from the contract.
Collectors normalise source material into records, claims link back to citations, and case files group related evidence.
Conflicting sources coexist. The interface can organise and quote them, but the final conclusion belongs to the reader.
- 01Source intakeCollect and preserve official or editorial provenance
- 02IdentityNormalise records, handle duplicates, and retain stable topic identity
- 03ClusteringGroup related claims without merging away disagreement
- 04Case fileAttach citations, dates, processing state, and unresolved evidence
- 05ReaderInspect the record and decide without a generated verdict
06 / Decisions and trade-offs
What I chose, what I rejected, and what the choice costs.
DecisionRejectedTrade-off
Preserve source roles and citations through every transformation.
Flatten all retrieved text before clustering and restore provenance at the end.
The data model and ingestion work are heavier, but the reader can inspect the actual record.
Group evidence without producing a final verdict.
Generate a confidence score or true-or-false label for each case file.
The product gives less immediate closure, but it does not manufacture authority the sources cannot support.
Treat incomplete generation as workflow state.
Suppress failed records behind an internal promotable flag.
The interface must explain more operational uncertainty, while silent disappearance becomes less likely.
07 / Evidence
The product exists. A stable quality denominator does not yet.
No stable public corpus count or quality benchmark is published yet. The case study reports the architecture and its boundary without inventing a score.
No publishable outcome or usage denominatorThe real product recording and captures establish that the source-led interface exists. They do not establish coverage, neutrality, or correctness across a stable corpus, so those numbers are absent.
08 / What failed
The failures are part of the architecture record.
01 Some source jobs failed silently
- What I saw
- A source could disappear from the visible record without a useful explanation.
- Why
- PIB and other source failures were swallowed inside generation or ingestion paths.
- What changed
- Failure state was separated from editorial eligibility and included in the workflow audit.
- Still true
- Source-specific reliability still needs stable operational monitoring.
02 Repeated ingestion created stale claims
- What I saw
- Duplicated or outdated material could survive beside a newer version of the same claim.
- Why
- Topic identity and duplicate handling were not strong enough across repeated collection runs.
- What changed
- Stable identity and duplicate handling moved ahead of clustering and publication.
- Still true
- No publishable corpus-quality benchmark yet proves the policy across the full record.
03 A gate suppressed more than it explained
- What I saw
- The promotable flag could keep a record out of view without making the underlying failure legible.
- Why
- Publishing eligibility and processing health were coupled into one suppressive field.
- What changed
- The suppressive gate was removed from the product contract and incomplete state remains visible.
- Still true
- Database workflow gaps still need explicit recovery tests before the record can be called operationally complete.
09 / Limits and future
What the product cannot do yet, beside what may come next.
Current limitations
- There is no stable public corpus export or quality benchmark, so no corpus size, freshness, or clustering score is published.
- Source availability and publisher formatting can still break ingestion in project-specific ways.
- The current product is a public-record organiser, not a newsroom, fact-checking authority, or substitute for primary-source reading.
- Committed main at bf4606f is the source boundary; current working-tree configuration changes are excluded.
Deliberate boundaries
- Issue a true-or-false verdict.
- Rank sources or assign sentiment as a substitute for evidence.
Stable corpus audit
Produce a repeatable export with source, duplicate, freshness, and unresolved-record denominators before publishing coverage claims.
Source-specific recovery
Make source failures visible, retryable, and attributable without turning operational health into an editorial ranking.
Database workflow repair
Close the known persistence and lifecycle gaps, then verify a complete source-to-case-file run from committed state.
10 / Stack and sources
The systems underneath it, and where this account comes from.
- Python
- FastAPI
- PostgreSQL
- source ingestion
- citation graph
Audited internallyTathya committed repository history and product docs
Audited internallyReal Tathya product recording and responsive captures
PublicPublished Tathya product